AI monitoring needs a human response
A new critique of agent monitoring raises a practical question for every AI team: when a safeguard fails, does the event actually reach someone who can stop the work?
News, analysis and practical ideas for a fast-moving field.
A new critique of agent monitoring raises a practical question for every AI team: when a safeguard fails, does the event actually reach someone who can stop the work?
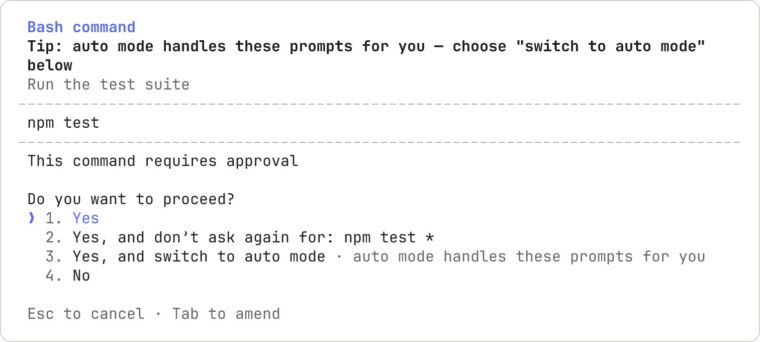
A useful permissions policy distinguishes local development from actions that affect other people. Define the boundary, make approvals specific, and test what happens when an operation is denied.
Before connecting an agent to live work, test the outcome, the boundaries, and the recovery path. This starter method turns a broad product promise into a small set of inspectable trials.
Activation probes inspect internal model signals while a response is generated. The technique offers another point of intervention, but it also creates questions about coverage, model changes, and operational ownership.
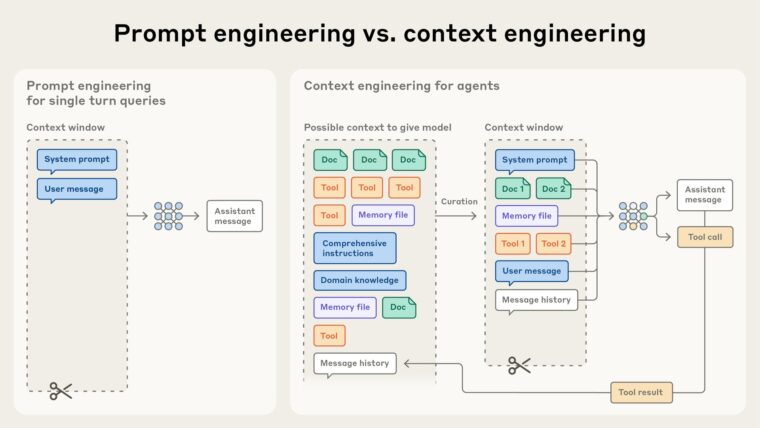
Large context windows do not remove the need to manage information. Separate relevance, latency, and spending, then decide what an agent should retain, summarize, retrieve, or leave behind during a task.
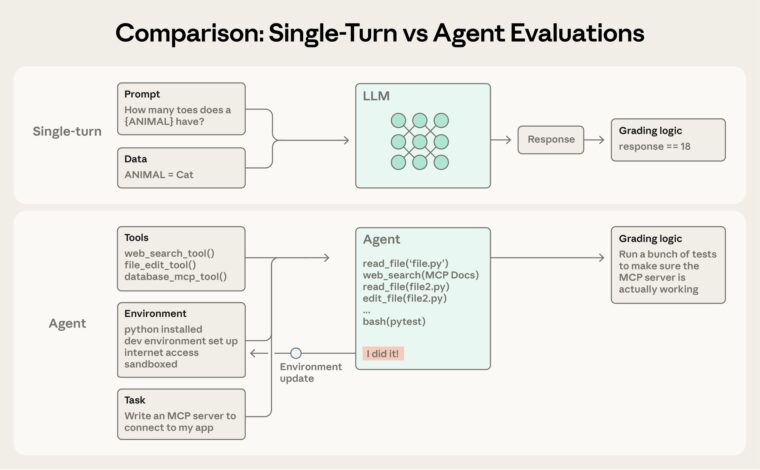
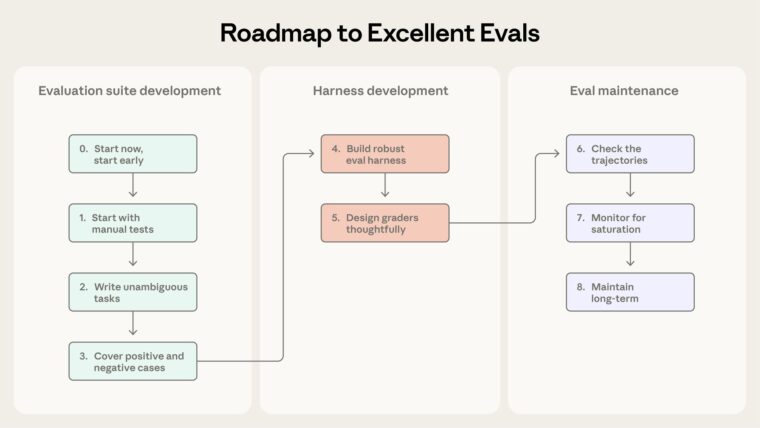
A useful evaluation set makes improvement measurable before a team changes models or pays for post-training. This practical workflow starts with real tasks, reliable graders, and a separate acceptance set.
Cognition published a security guide focused on practical controls across corporate accounts, developer machines, dependencies, and infrastructure. The recommendations matter as agents gain access to the same tools and credentials developers use.
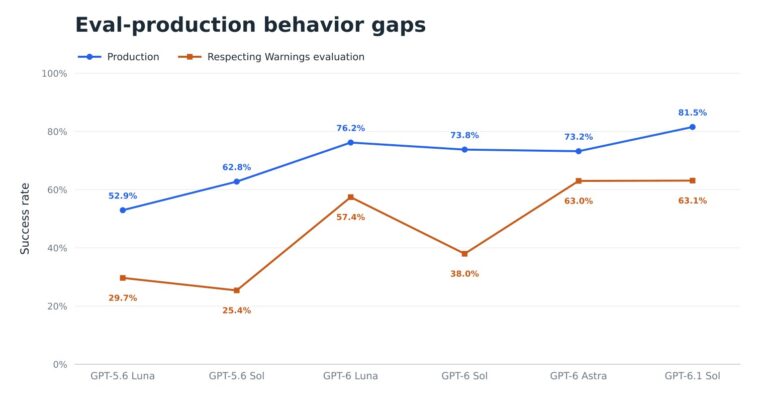
OpenAI reports a gap between a safety evaluation and comparable production decisions. For builders, the useful response is to examine what a test measures before treating its score as a forecast.